ORCHESTRATION POSTMORTEM: SIX HOURS, ZERO ROWS
Four terminals burned 6.5 hours and returned zero rows. This orchestration postmortem exposes the retry loop, dead lane, and fixes that now stop the waste.
 DAAVILE Research Lab
November 14, 2026
11 min
Article
The orchestration postmortem starts with a bad surprise: four busy terminals, 6.5 hours, and zero registered rows. On 2026-10-31, we dispatched two background workers to a mutation round. One champion strategy fed a ladder of candidate variants across four terminals, with about six hours of wall time.
When the operator stopped the round at 14:03, the scorecard showed roughly 250 requeue cycles and 13 full backtests that were never registered. The campaign card hadn't moved a single row. Six and a half hours of fleet compute bought nothing.
This run failed without crashing, and that was the dangerous part. There was no error page and no red alert, only busy machines and an empty card. The failure became the spine of this article; the fixed rules it bought are the ending.
We read this failure against the lab's broader three-phase testing protocol. The protocol separates clean, delayed, and robustness runs; this postmortem focuses on the plumbing around them.
#The orchestration postmortem begins with an over-ambitious brief
The brief was ambitious on paper. Each worker had to find at least twelve qualifying candidates and climb from the first depth level to the second, using four terminals inside roughly six hours.
Two workers split the fleet. One took two terminals and an explicit instruction to hunt high-drawdown-group variants. The other took the remaining two and subtler clues.
Both started at 06:38 without a pinned model. Each worker chose its own reasoning model at spawn time, so nobody downstream could tell which model produced which behavior.
Communication was sparse from the first minute. Worker B sent a heartbeat at 06:42 saying "investigating." Worker A sent one at 07:18 saying "implementing."
Neither worker sent another message. There was no completion, no escalation, and no further heartbeat. In hindsight, that silence was the first failure signal, and nobody was watching for it.
A silent run is already a lost run; the logs only show it after the fact.
#The six-and-a-half-hour timeline shows one early win and a long retry storm
The driver log for the round runs 1,330 lines. Every marker below is a logged event in that log or in the run inbox; none is inferred.
| Time | Event | What it meant |
|---|---|---|
| 06:38 | Both workers dispatched | Four terminals committed, ~6 h window opened |
| 06:42 | Heartbeat from worker B | "investigating" — the last message B ever sent |
| 07:13–07:30 | 13 runs banked raw on lane A's primary terminal | 12 unique candidates, one four-week window in early 2026 |
| 07:18 | Heartbeat from worker A | "implementing" — the last message A ever sent |
| 07:30:25 | Requue storm begins | One unprovable cell starts looping to the front of the queue |
| 07:30–14:02 | ~250+ cycles, zero progress | Launch fails, full backtest runs, journal check fails, requeue — forever |
| 14:02:21 | Storm ends | Nothing registered; both workers stopped by operator order |
| 14:03 | Aftermath | Three of four terminals empty; the primary holds leftover static charts |
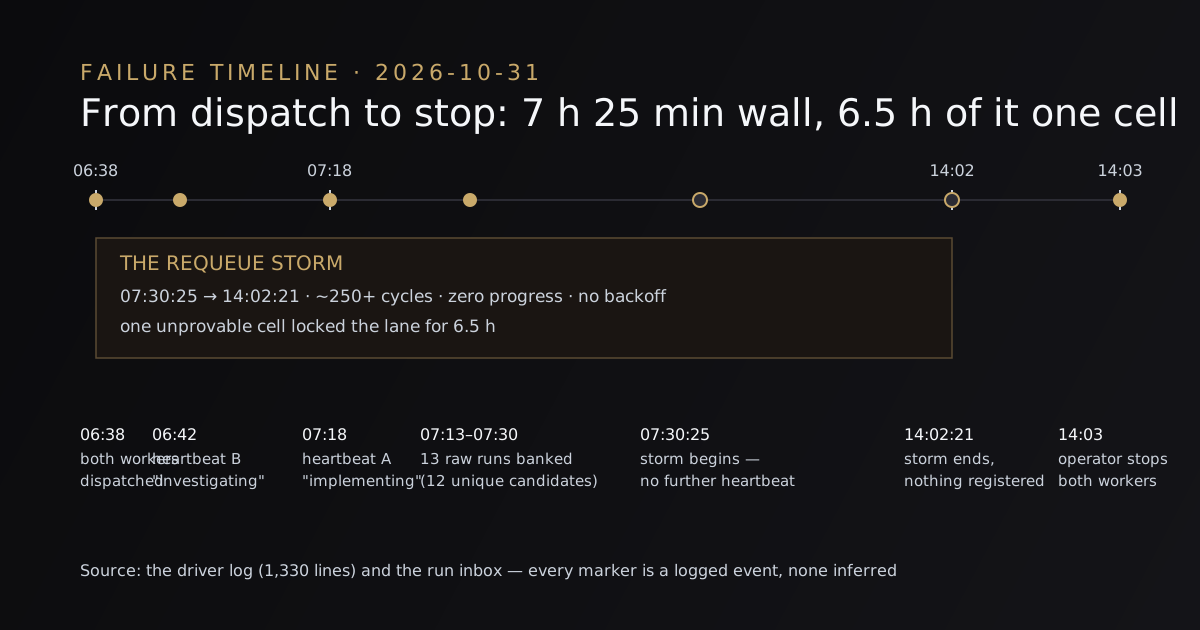
All productive work finished by 07:30. Thirteen raw runs were banked inside seventeen minutes on one terminal that did exactly what it was told.
Everything after 07:30:25 was the same cell requeued for 6.5 hours. The workers stopped by operator order at 14:03; both returned a stopped state with an outcome of failed and a liveness of exited. Nothing in the system raised a hand.
#A five-step requeue loop turned one unprovable cell into 6.5 hours of waste
The storm had one cell at its center: a deep-points variant of one of the first worker's candidates. It repeated a five-step loop with no exit condition.
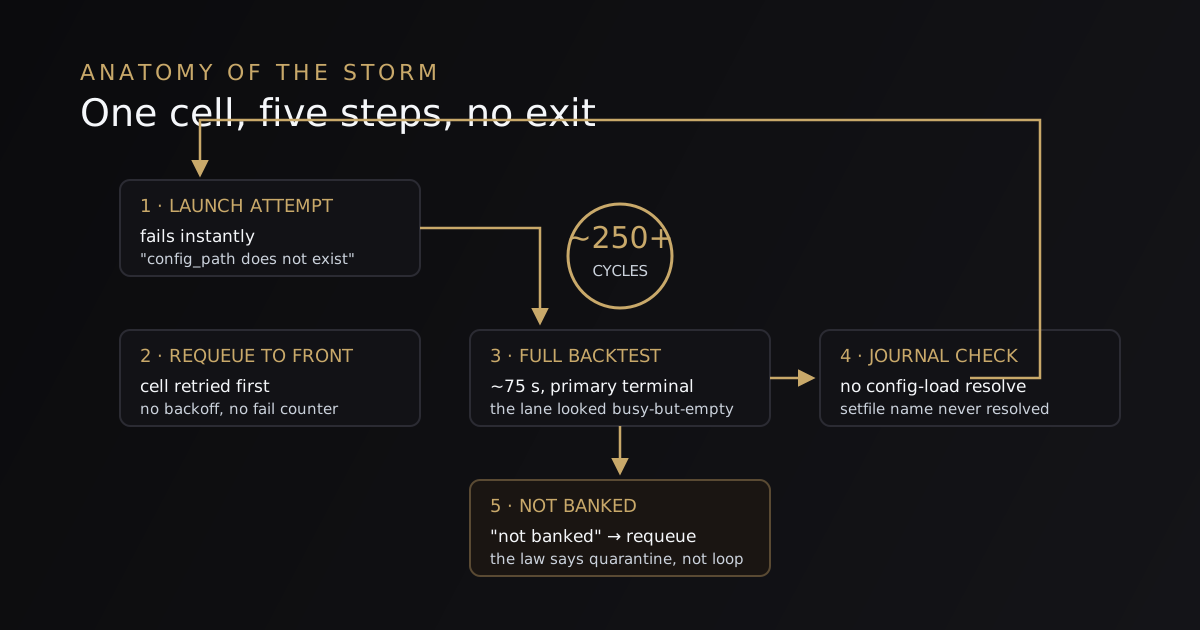
| Step | What happened | What should have happened |
|---|---|---|
| 1 · Launch attempt | Fails instantly: the config path does not exist | Run the prepare chain first — inputs, then config |
| 2 · Requeue | Cell goes back to the front of the queue | Count the attempt; three and quarantine |
| 3 · Full backtest | ~75 s on the primary terminal, every cycle | Same — the compute was never the problem |
| 4 · Journal check | No config-load resolve for the setfile | Same — this check was correct and is the law |
| 5 · Verdict | "Not banked" → requeue to front | Mark journal-unproven, move on, escalate |
The loop was a doctrine failure before it was a code failure. The lab's two-step staging law requires a candidate's setfile to exist in every agent sandbox directory under its exact configuration name.
The backtest ran on the primary terminal, but the journal recorded no config-load resolve for that setfile. The law held for the window that produced the thirteen banked runs and failed for the storm cell. A staging path and name mismatch inside the worker's own code was never isolated because the worker was stopped.
The correct response was to quarantine an unprovable cell after a fixed number of attempts. Don't bank it. Move on and escalate. Instead, the driver requeued it forever with no backoff, fail counter, or escalation path.
The terminals looked busy but were empty. One failed instantly; the other reran the same full backtest every cycle.
We call this failure a requeue storm. It belongs to the same family as the fleet-sweep "blocking read wedge" because it returns wherever a retry path exists without a budget. A retry without a budget is a while-loop that spends machines.
Compute cost makes the failure expensive. A full backtest on the primary terminal took roughly seventy-five seconds, and the storm consumed hours of it for a cell that could never be banked.
The second terminal burned its evening failing instantly on a config path that never existed. The two terminals on the dead lane idled at zero. Four machines produced one useful window of seventeen minutes, and an operator had to escalate at two in the afternoon to find out.
A counter that counted to three would have prevented those costs.
#One lane died silently while three others never produced a registered row
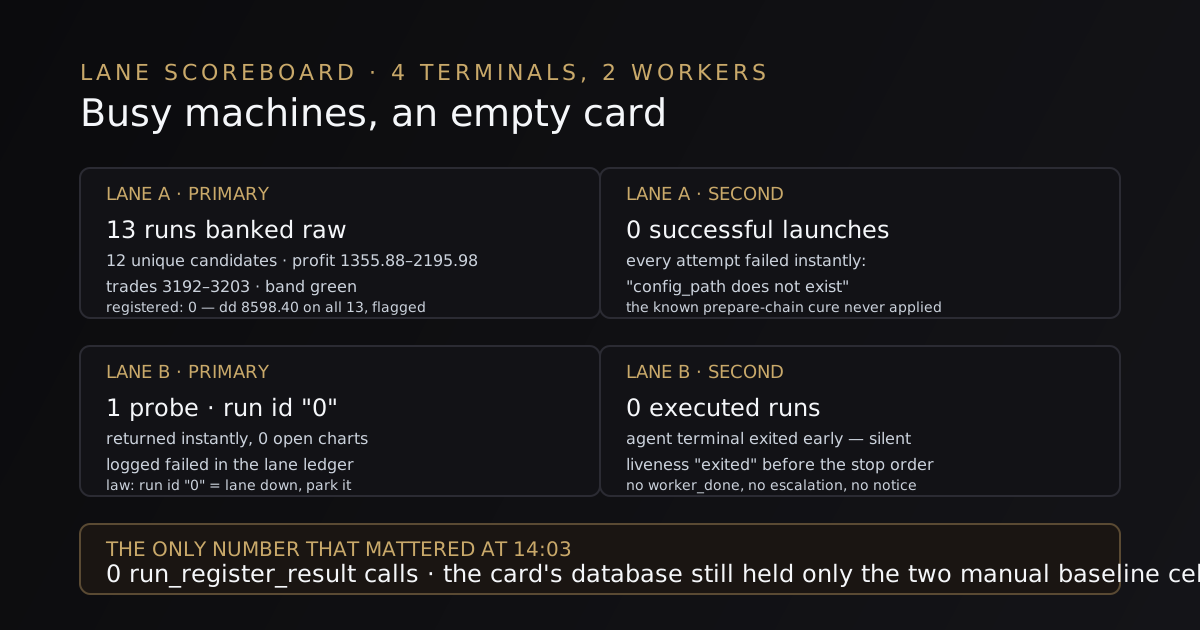
The second worker's lane died without producing a storm. Its agent terminal exited early, with liveness marked "exited" before the stop order arrived.
Its only probe returned a run id of "0" instantly and opened zero charts. The lane's own ledger logged it as failed. The worker produced a tools directory, one candidate, and zero executed runs. A lane that cannot launch is absent; treat it as down and park it.
The prepare chain was the known cure: prepare inputs, prepare the configuration, then launch. A zero run id means the lane is down and must be parked. Neither worker applied that rule.
The orchestrator acknowledged two heartbeats, then stopped checking worker liveness. It didn't poll again until the operator escalated at about 14:00. Both workers already carried unverifiable liveness and a required-action flag that went unactioned.
No watchdog, autosync, or auditor daemons were running, and the health file had been stale for days. A worker can die silently. The coordinator cannot be allowed to.
The same failure shape later surfaced in the data-integrity audit. A health check that only reads a registry can still miss a lane that died outside it.
#The run produced 13 raw backtests but 0 registered results
The useful output was small, but it wasn't empty. Thirteen raw backtests existed; none had crossed the registration door.
| Fact | Value | Status at 14:03 |
|---|---|---|
| Raw runs banked | 13 (12 unique candidates) | Exist as raw reports and log lines only |
| Window | Four weeks in early 2026 | Phase-one condition |
| Profit range | 1,355.88 – 2,195.98 | Unverified — not quotable yet |
| Trade counts | 3,192 – 3,203 | Band: green |
| Max equity drawdown | 8,598.40 on all 13 | Identical across all 13 — flagged for auditor eyes |
| Registration calls | 0 | The card still held only the two manual baseline cells |
Thirteen full backtests existed only as raw reports and log lines. The 1,330-line driver log contained zero registration calls, and the campaign card still held only the two manual baseline cells.
The storm cell's number never arrived, and the thirteen runs that did arrive never moved. All 13 carried the same 8,598.40 maximum equity drawdown. That may fit a shared baseline floor, but it was unproven, so it stayed out of the record.
After the stop, three of the four terminals stood empty. The primary held leftover static charts from the killed loop: gold, fifteen-minute timeframe, one per chart. The next driver run had to close them one by one.
#Six root causes explain why busy terminals stayed empty
Six failures compounded. A bad cell met a broken staging path, three dead lanes, weak supervision, and a brief that allowed one stall to crowd out every other worker.
- Unbounded requeue loop, no circuit breaker. One unprovable cell locked a worker for 6.5 hours. No max-attempts counter, no escalation path, no completion message ever sent.
- Staging-law breach on the storm cell. The two-step setfile law held for one window and failed for another: a path and name mismatch inside the worker's own code, never isolated because the worker was stopped.
- Three of four lanes never launched a single successful run. One failed every attempt on a missing config path; one answered with run id "0"; one never executed anything. The known prepare-chain cure sat written down, unapplied.
- The second worker died silently. A structured background session with no pinned model went to "exited" liveness, and nothing on the coordinator side noticed for hours.
- No supervision on the orchestrator side. Two heartbeats were acknowledged and then nobody polled again until the operator escalated. Required actions sat unactioned; the watchdog daemons were not running.
- Scope was unrealistic for the window. Twelve qualifying candidates per worker, two ladder levels, four terminals in ~6 hours, with the launch protocol broken on three of four lanes, and a design that let one bad cell starve every other lane.
#Five circuit breakers now stop failed runs from burning the fleet
We adopted the recovery rules the same night, and they remain standing law:
- Never requeue-front the same cell-and-candidate more than 3 times. Then mark it journal-unproven or launch-failed and move on. Escalate through the inbox if a lane is dead for more than 30 minutes.
- No banked result without proof. Before any launch on a fragile lane, run the prepare chain and require a non-zero run id plus the config-load resolve in the journal. Run id "0" means the lane is down: park it.
- The coordinator polls liveness at least every 15 minutes while a run is live, and acts on required-action flags instead of acknowledging heartbeats.
- Register only what can be proven. Banked cells need journal proof and verified-report notes. The thirteen probe runs stay unregistered until the auditor proves them, including the identical-drawdown flag.
- Isolate failures per lane. One bad cell must never be able to starve the other lanes.
The successor round launched the next day with prove-first evidence, a fifteen-minute heartbeat, a three-attempt circuit breaker per cell, and park-on-zero for dead lanes. Thirteen probe runs from that failed evening remain unregistered pending auditor proof, including the identical-drawdown flag. We kept that scar visible so nobody forgets what an unproven row costs. The evening's last useful product was a driver that can no longer spend six hours proving nothing.
The failure is now part of the operating record. You can compare the current campaign state with the published DAAVILEFX results.
- Retry only within a hard budget: the storm cell requeued roughly 250 times; the breaker now allows 3 attempts.
- Register only proven results: the 13 raw runs stay unregistered until the auditor proves them.
- Park a dead lane before it consumes the round: run id "0" means the lane is down.
Open the quantum dashboard to see the live evidence and the gates that now prevent a silent six-hour waste.
#Questions we get asked
#What happened during the 6.5-hour mutation round?
It was a requeue loop. Four terminals and two workers kept the round busy, but one unprovable cell was requeued roughly 250 times. The run ended with 13 raw backtests and 0 registered results.
#Why did the campaign card stay empty?
The journal could not prove the configuration loaded. The backtests ran, but the lab's rules do not allow an unproven result to be registered.
#What stops the requeue loop now?
A three-attempt circuit breaker now stops it. The coordinator checks liveness every 15 minutes and parks a lane that returns run id "0".
#Did the 13 raw runs become published results?
No. All 13 remain unregistered until the auditor proves them, including the identical 8,598.40 drawdown across every run.